Embed TongFlow media workflow editor in DSH: each asset is generated by an independent workflow file, with the AI Agent handling project structure and asset management.

- Language
- TypeScript
- License
- AGPL-3.0
- Branch
- main
Install
$ dsh plugin --profile web add dsh-tongflowRun the command above in your terminal to install this plugin via the dsh CLI. You can switch Profile in the top-right corner. New to dsh? Read the beginner tutorial
Install via your agent
Install the DeepSeek Harness plugin tong-io/tongflow/packages/dsh-tongflow for me: review the repository at https://github.com/tong-io/tongflow first, then run the install command and verify the plugin loads successfully.
Paste this instruction to the DSH Web GUI assistant — it will install and verify for you.
One-line Description
Embed the TongFlow media workflow editor into DSH: when users create images, audio, video, or 3D content using the DSH Agent, each asset is generated from an independent workflow file, with the Agent responsible for project structure and asset organization. Users can directly fine-tune on the canvas and rerun.
Core Capabilities
- Create Studio project folders with custom structure (no fixed template, designed collaboratively by Agent and user)
- Drive all image, audio, video, and 3D asset generation using
.tongflow.jsonworkflow files; output files are placed alongside the workflow and do not overwrite historical results - Provide node directory and node descriptions so the Agent knows what node types, connection rules, configuration fields, and available plugins exist
- Let the Agent review generated results via
tongflow_look(images) andtongflow_perceive(video/audio/image understanding) before proceeding to the next step - Built-in paid plugin confirmation mechanism and project/plugin management tools to avoid accidental charges
- Auto-clone official plugins at startup and maintain venv, keeping the canvas node directory in sync with the TongFlow official version
Technical Implementation
- Language: TypeScript (node-side + browser-side CJS bundle in one)
- Key Dependencies:
@deepseek-ai/cordis,@deepseek-ai/dsh-*suite (agent / tools / skills / webserver / llm / jobs / system-prompt),tongflow(same repo workspace package),@deepseek-ai/schemastery - Architecture Pattern: Cordis plugin, inserting
tongflownodes into cordis viadsh.bundle.patch; useagent/pre-stepevent to determine if the current session enters Studio mode (first message starts with@tongflow), and only register tongflow_* tools, skills, and system prompt segments for Studio sessions - Entry Files:
src/index.ts(Node-sideapply) +src/client/index.ts(browser-side bundle), injected into host viacordis.patch.yml
Use Cases
When using DSH for storyboard layouts, short videos, ad assets, music MVs, character profile sets, 3D resource packs, or other batched, iterative AI-generated content, this plugin transforms "asset production" from one-time chat results into saveable, rerunnable, manually adjustable workflows; regular conversational needs (coding, information lookup) don't need it.
Prerequisites and Compatibility
| Dependency | Minimum Version | Description |
|---|---|---|
| DSH | >= 0.1.0-rc.7 | All @deepseek-ai/dsh-* companion dependencies require this version |
| Node | >= 22.19.0 | Consistent with DSH's own requirements (stated in README) |
| Python | >= 3.10 | First startup will automatically create ~/.dsh/tongflow/venv and install tongflow SDK; pythonPath can be specified |
| Git | Required | Official plugins are shallow-cloned at startup via git |
| FFmpeg | Recommended | Used for video contact sheet generation |
Installation
dsh plugin --profile web add github:tong-io/tongflow/packages/dsh-tongflow
Configuration Options
| Config | Type | Description | Default |
|---|---|---|---|
| studioRoot | string | Studio data root directory, storing projects, virtual environments, cloned plugins, cache | <DSH_HOME>/tongflow (i.e., ~/.dsh/tongflow) |
| pythonPath | string | Python executable path (≥ 3.10) for creating Studio venv; leave empty to auto-detect in PATH | Auto-detect (python3.13 → python3.10 → python) |
| sdkSpec | string | pip spec to install in Studio venv, e.g., tongflow==0.3.0, or -e /path/to/sdk for development | tongflow==0.3.0 |
| pluginOrg | string | Git organization address for official plugins (clone source) | https://github.com/tong-io |
| pluginGitUrls | object | Custom plugin id → git URL mapping, for community or private plugins | {} |
| env | object | Environment variables injected into plugin subprocess (like API Key), recommended to use the "Plugins & Secrets" panel in Studio first | {} |
| maxConcurrentRuns | number | Maximum concurrent Workflow runs | 2 |
| httpPrefix | string | HTTP route prefix used by Studio and canvas | /tongflow |
| locale | string | Interface language for embedded canvas | en |
| autoInstallOfficial | boolean | Whether to auto shallow-clone missing official plugins at startup (only clone, deploy/charge on-demand) | true |
FAQ
Q: What's the difference between this plugin and using TongFlow SaaS directly?
A: They share the same TongFlow engine, node directory, and ABI, but this runs in your local DSH: assets land on your hard drive, with the DSH Agent leading project structure and asset planning, and support for local tools/skills collaboration; the SaaS version doesn't have the Agent layer.
Q: I installed it but don't see tongflow_ tools in my session?*
A: Studio mode is not activated by default. Tools and Studio UI are only injected when the first message in a session starts with @tongflow; other sessions remain regular DSH as before the plugin was enabled.
Q: If I accidentally run a paid plugin, will I be charged?
A: When tongflow_workflow_run detects the workflow uses paid plugins (API-paid or Modal GPU), it must receive explicit user_confirmed: true to actually execute; otherwise it returns needs_confirmation listing involved plugins, billing method, whether keys are configured, and available alternatives; local plugins don't require confirmation.
Q: Can I run an image multiple times?
A: Yes. Each run generates a new numbered output file (e.g., mei_ref.01.png, mei_ref.02.png), never overwriting historical results; run records are written to <name>.runs.json; just run again after adjusting the workflow.
Q: Can workflows reference other assets?
A: Yes. Data nodes can directly write file paths (relative to workflow file ../style.md or project root characters/mei/x.png), or use {{path}} placeholder to embed text file content into prompt at runtime; URLs are passed to plugins as-is.
Q: What modalities are supported?
A: The node directory covers image, audio, video, and 3D modalities, with respective modality/ data nodes and transfer/compose/decompose/batch executable node categories; specific available plugins depend on your installed/auto-cloned TongFlow plugin list.
Q: What if I don't have Python installed?
A: The first startup will error out if Python ≥ 3.10 is not found; you can install official Python, use uv python install, or specify pythonPath in config.
Learning Curve
Intermediate — Users need to understand the "workflow as asset" design paradigm, node directory and connection rules, and have Python, Git, and (optional) FFmpeg ready; the plugin's installation command itself is simple.
Known Issues and Limitations
- If the system doesn't have Python ≥ 3.10 at startup, it will throw an error requiring installation or setting
pythonPath(src/engine/bootstrap.ts:83-86) - Official plugin cloning depends on Git; when
autoInstallOfficial=true, it pulls in the background asynchronously, during which the canvas node directory may be incomplete (src/studio.ts:65-72) tongflow_workflow_runwill refuse to execute paid plugins withoutuser_confirmed=true, requiring user confirmation again in the current session each time (src/tools/run-tools.ts:78)- Plugin uninstall won't clean up projects, venv, cloned plugins, and
env.jsonunder~/.dsh/tongflow; manual deletion required (no auto-cleanup logic found in source)



Demo Examples
| Workflow | Result |
|---|---|
Basic — Type text (Add), generate images (Transform), then blend them into one (Compose).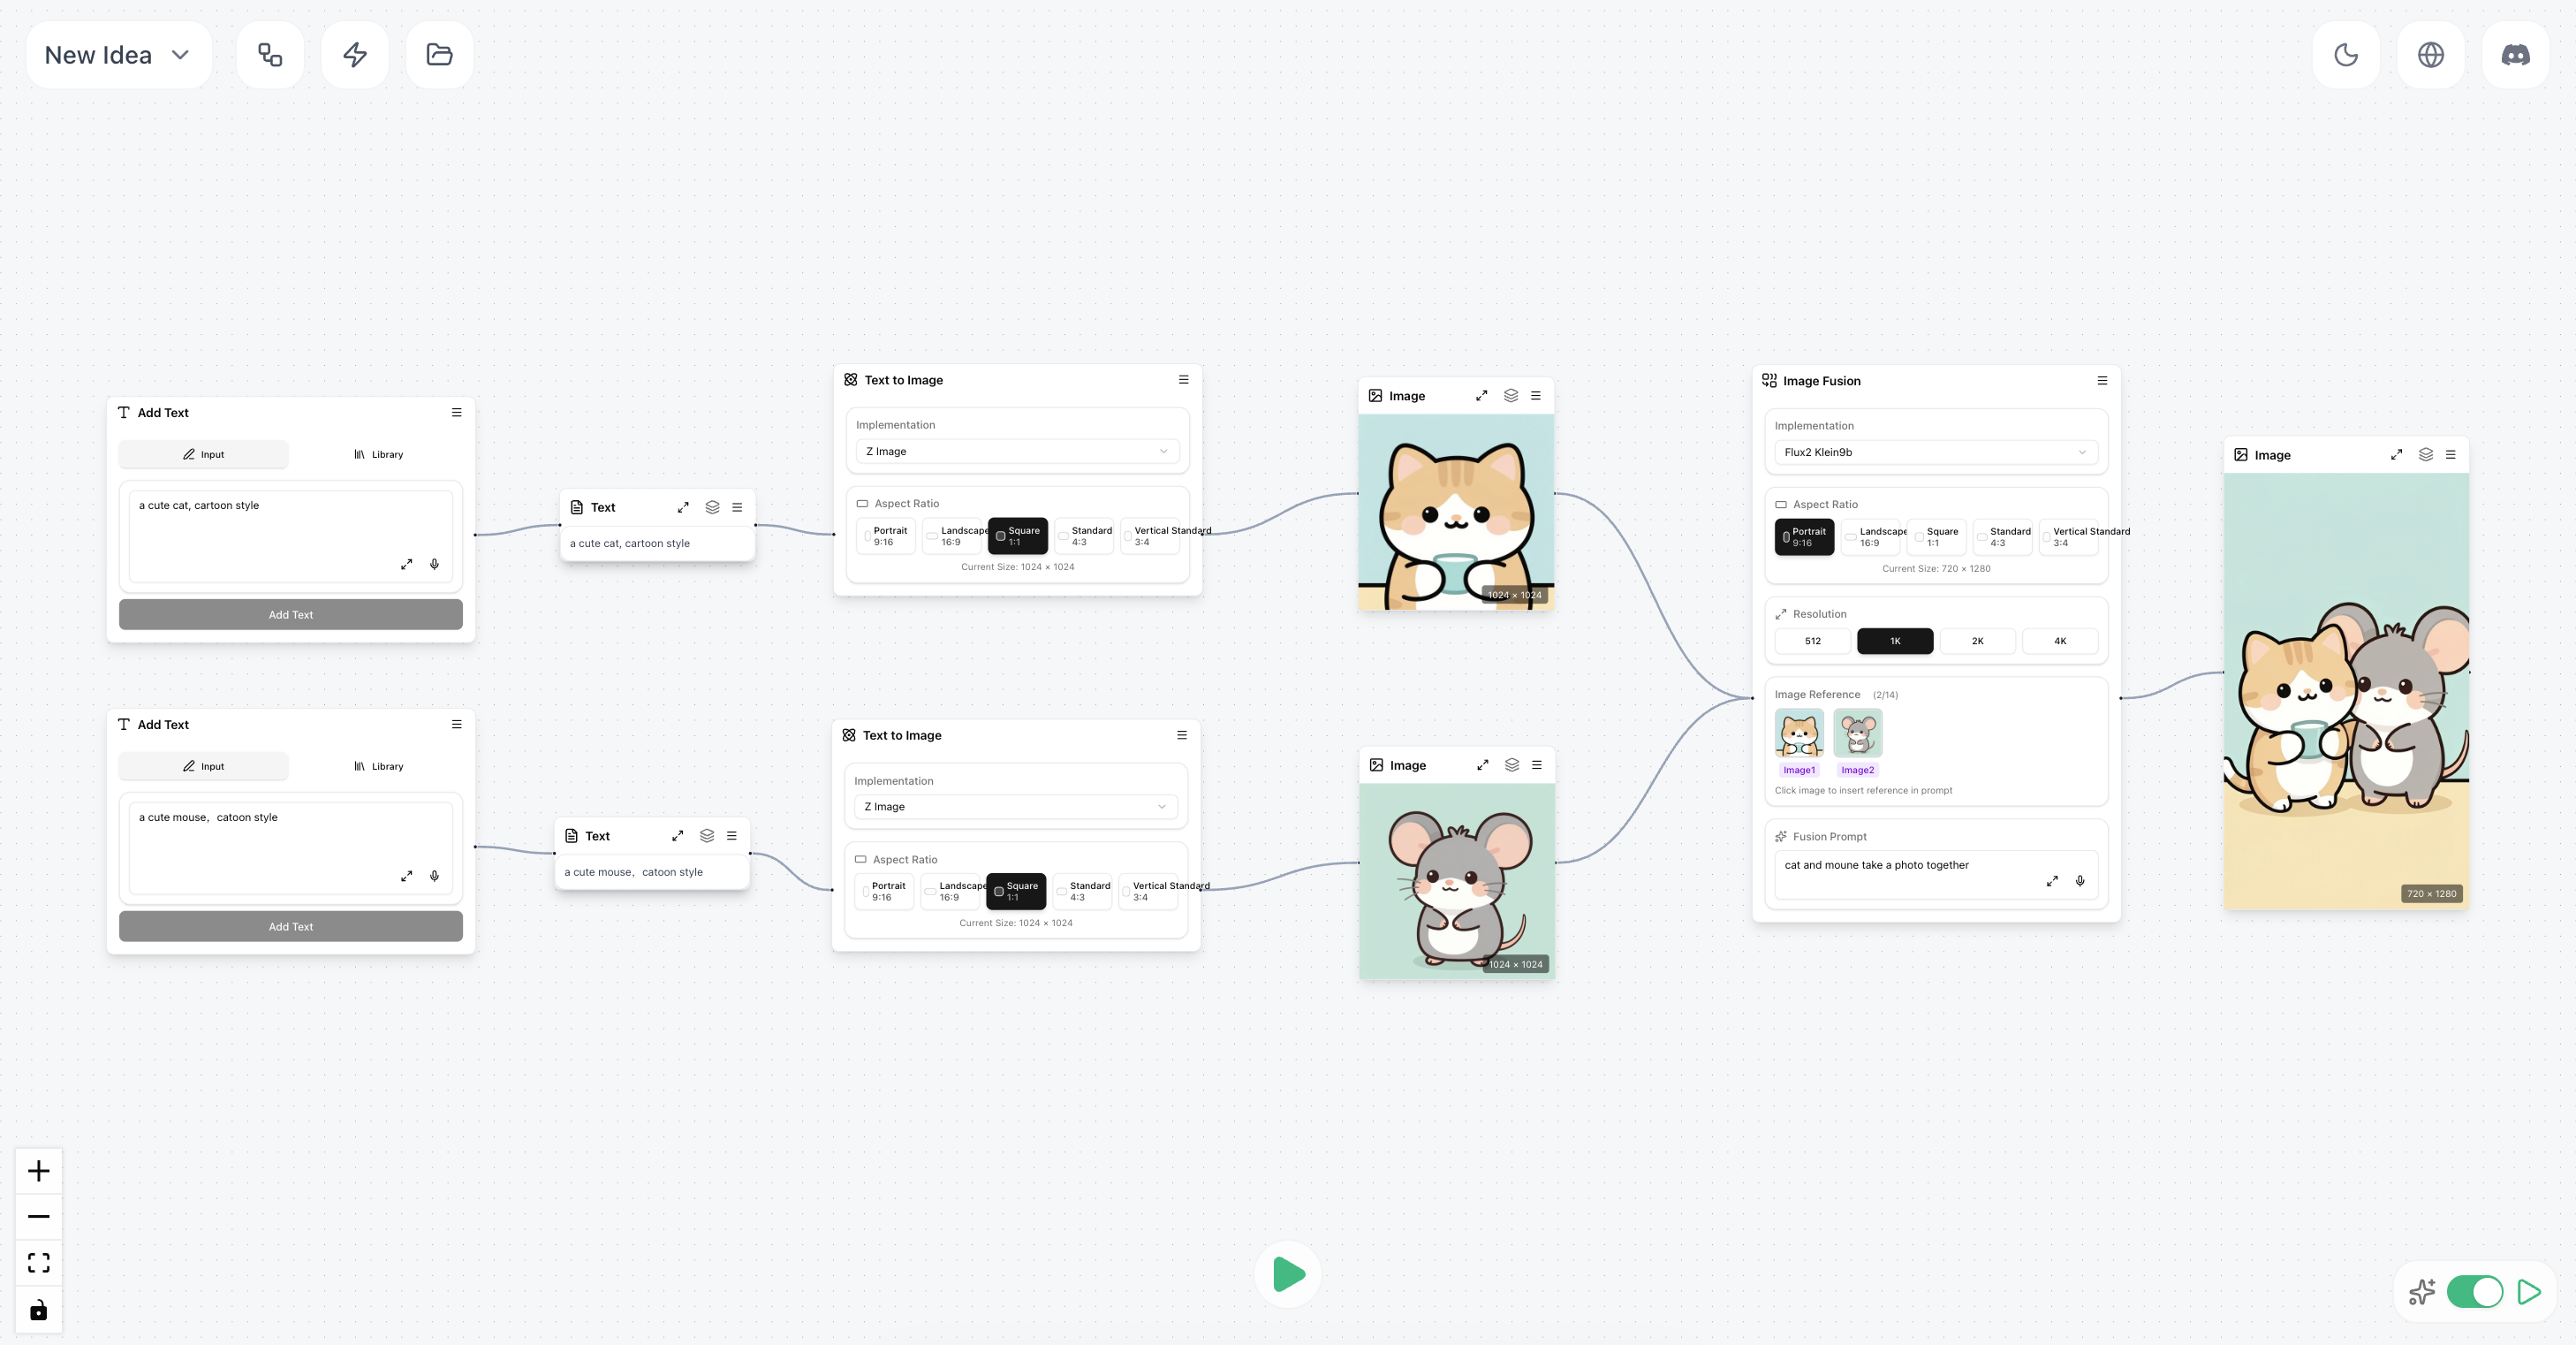 | 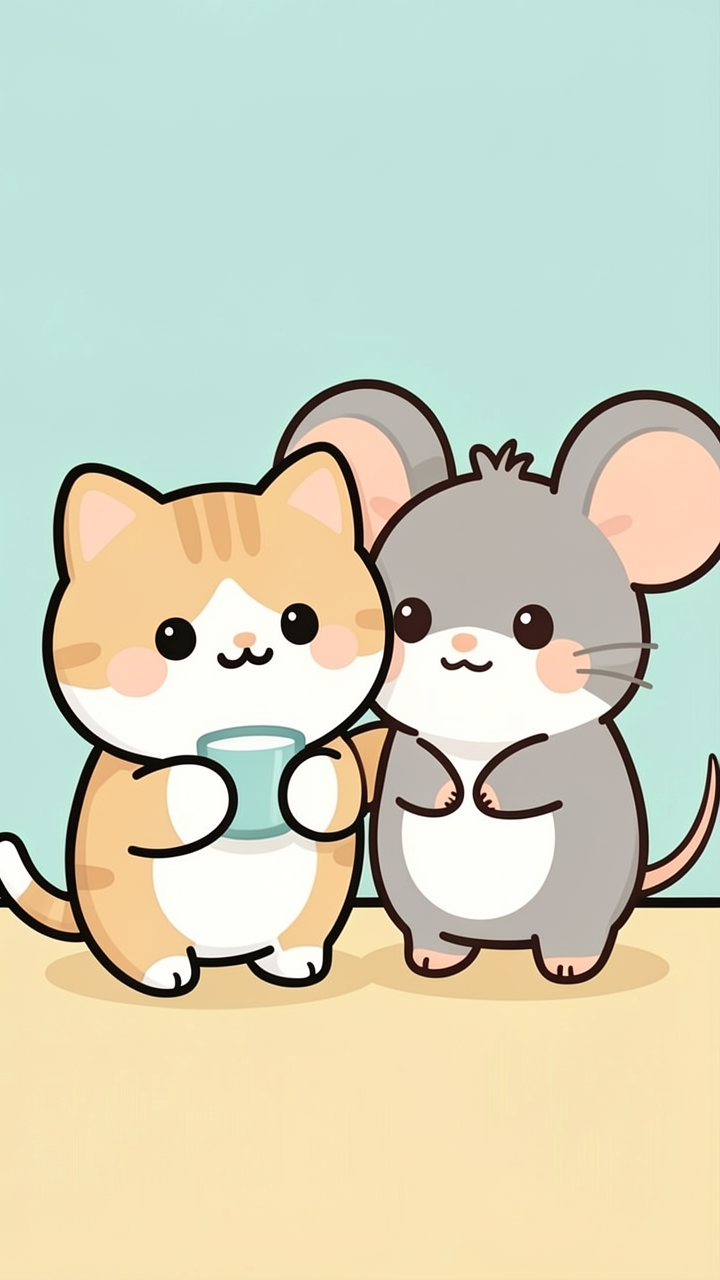 |
Intermediate — (Add topic → write script → generate speech) + (character description → generate image) → lip-synced video = talking-head avatar.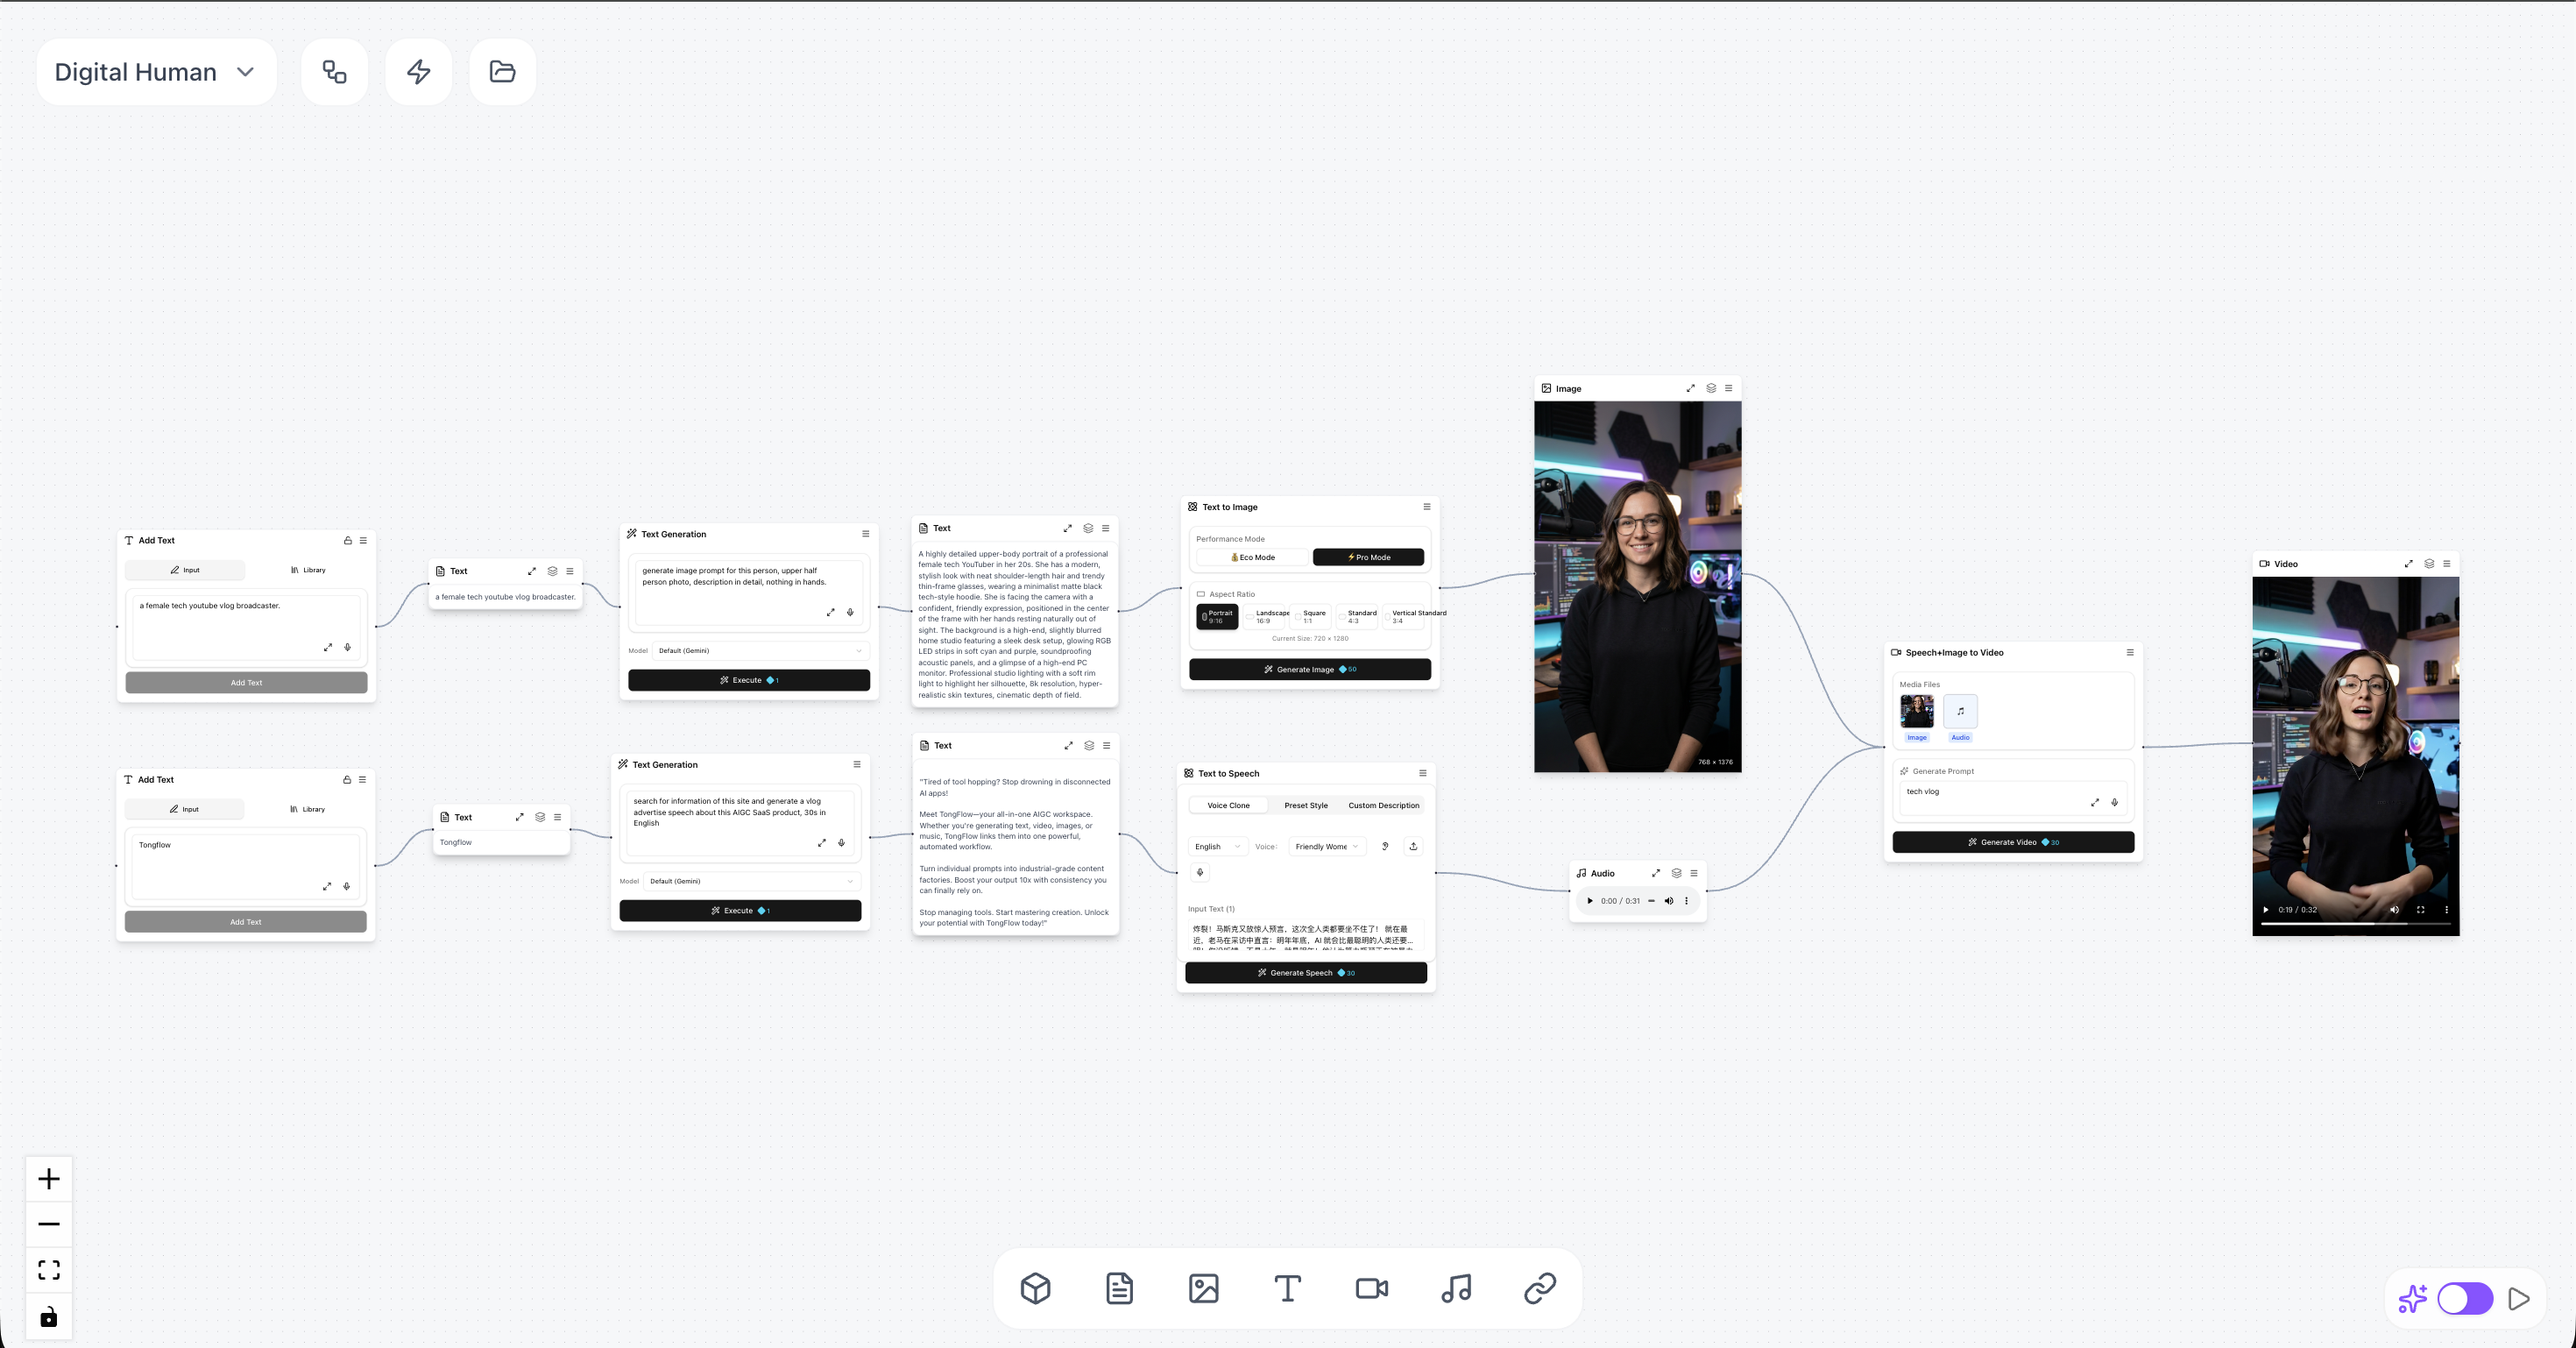 | |
Advanced — Generate lyrics + song + characters + scenes + storyboard → produce a music video.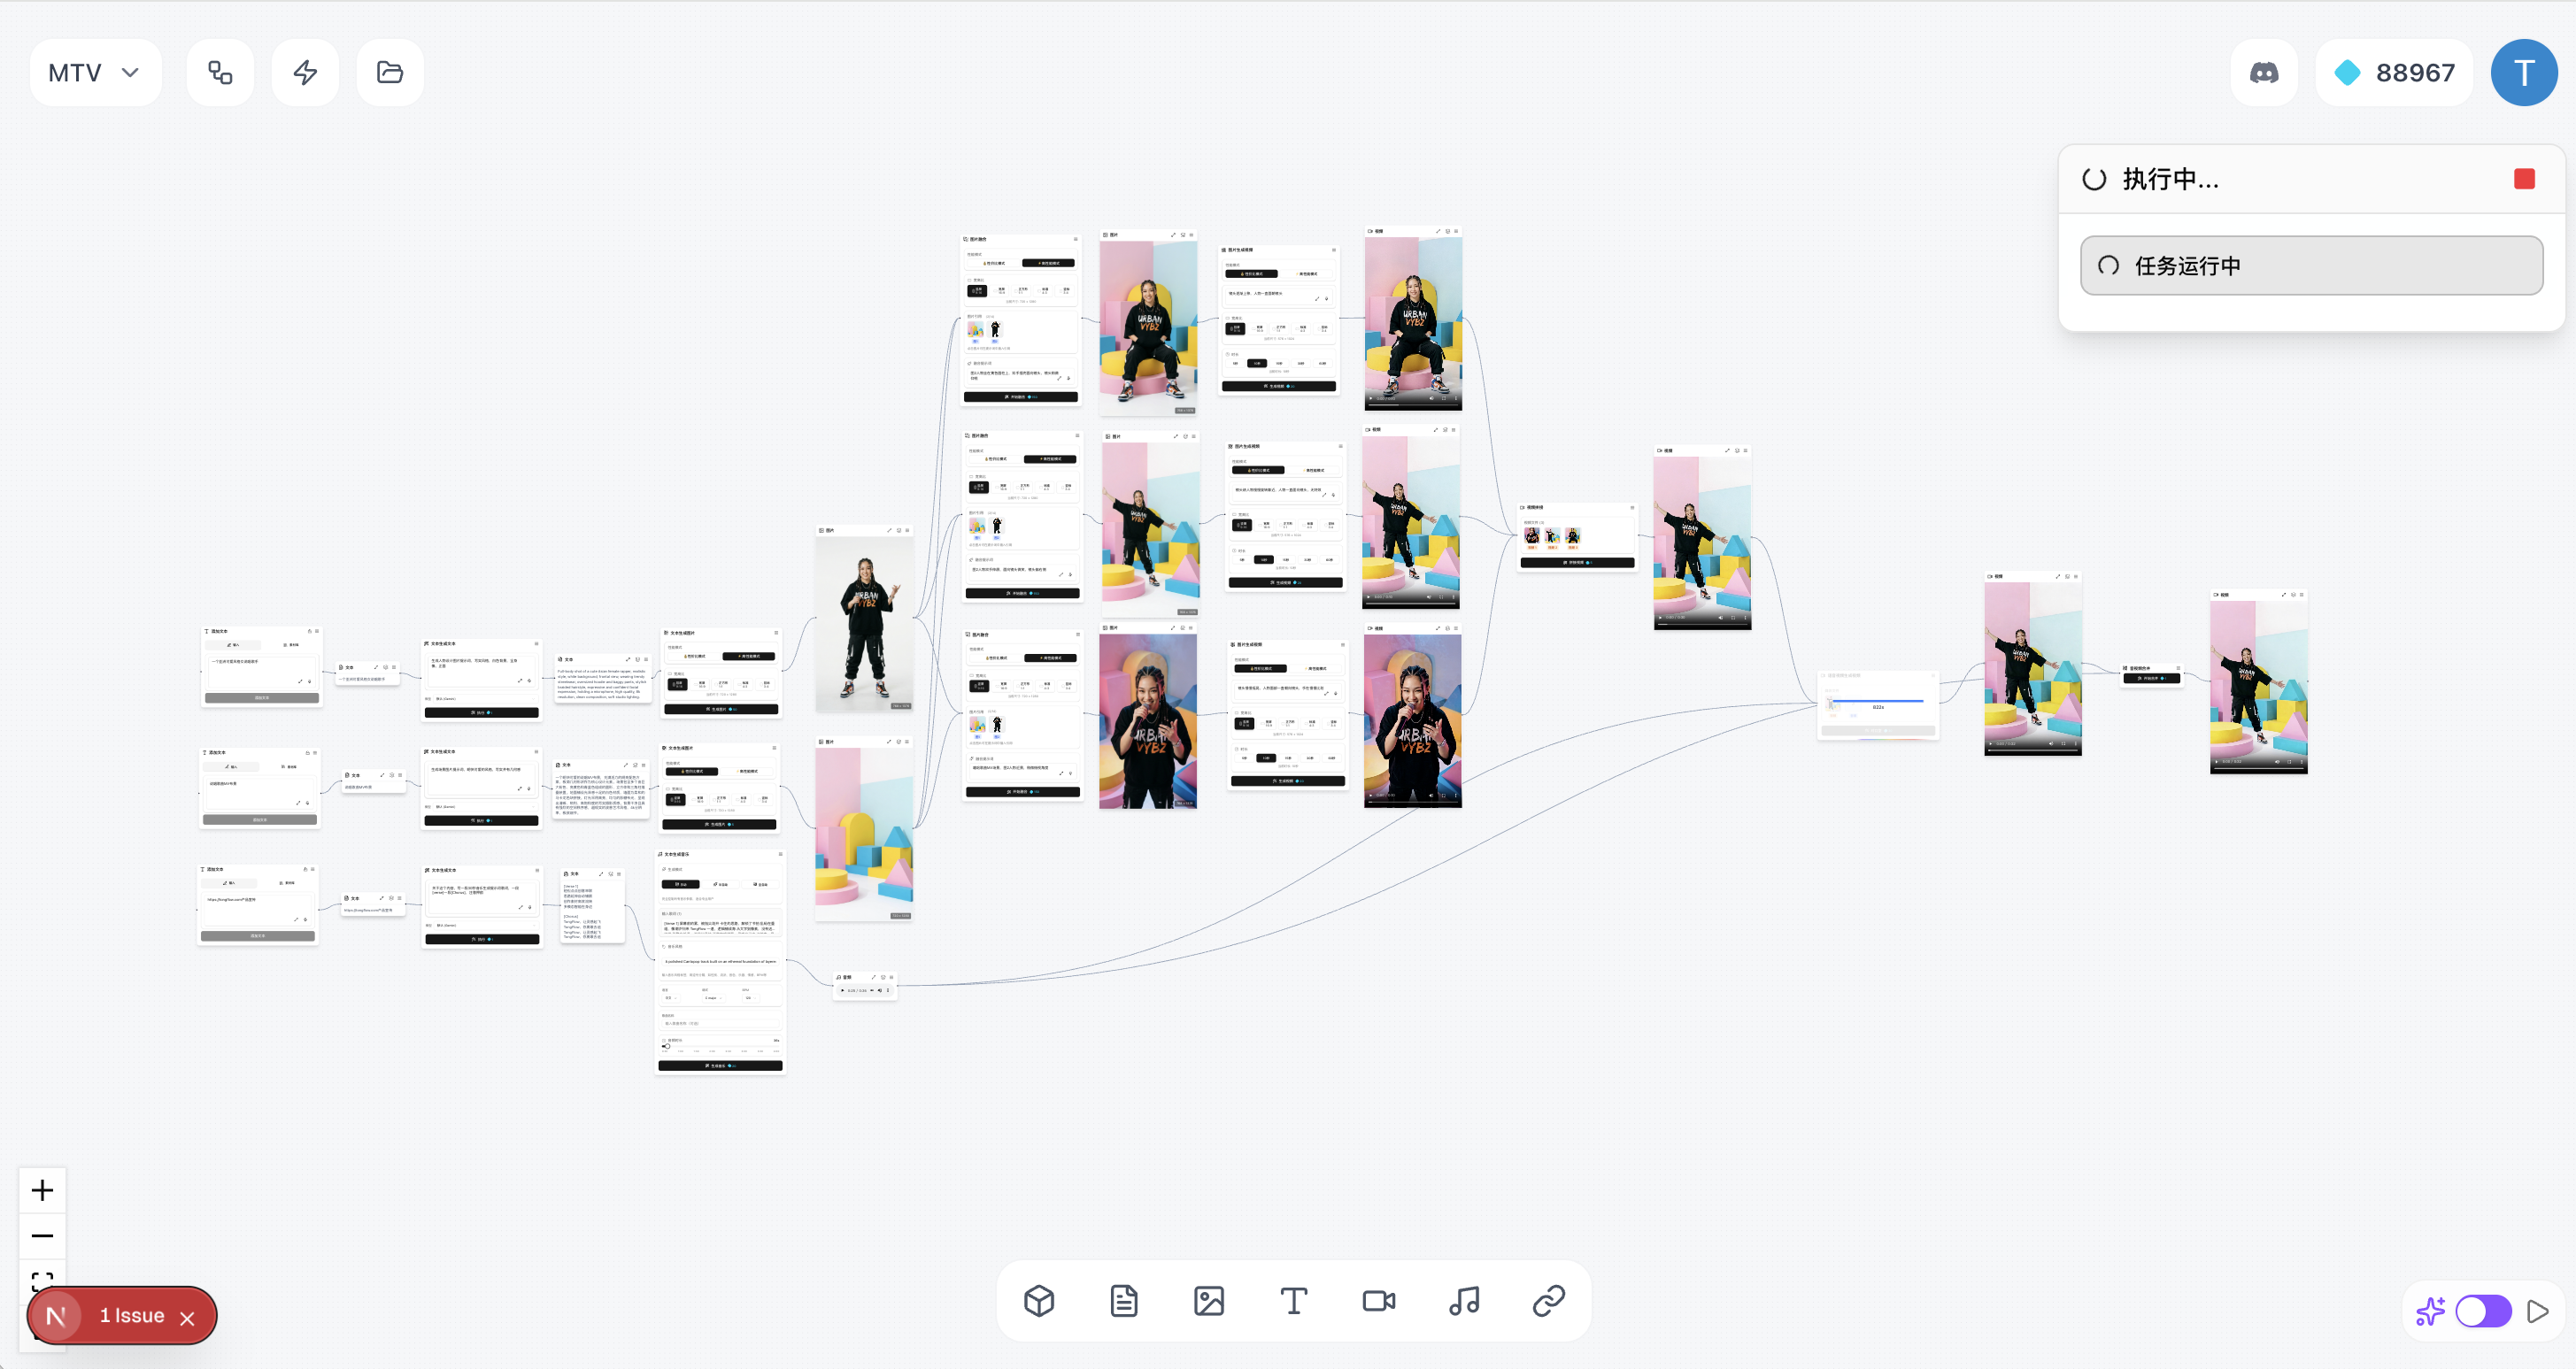 |
With TongFlow, you can expand your imagination and stretch your ideas with generative AI, just have a try now!
How To Start
The TongFlow desktop app is a lightweight (~10 MB) shell around the cloud studio at app.tongflow.com — install it, sign in, and start creating. The cloud studio also runs in any modern browser.
Step 1 — Install the desktop app
Download the installer for your platform, install it, and open it.
- macOS (Universal — Apple Silicon & Intel): TongFlow-mac-universal.dmg
- Windows: TongFlow-win-x64.msi
All builds are on the Releases page.
macOS: the builds are not yet notarized with Apple, so Gatekeeper will block the first launch ("TongFlow is damaged and can't be opened"). After moving the app to Applications, clear the quarantine flag once and it opens normally:
xattr -cr /Applications/TongFlow.appDownload from this page directly — installers passed through chat apps (e.g. WeChat) may be renamed or re-flagged.
Step 2 — Sign in and create
Sign in with Google or WeChat and start creating — the cloud studio manages plugins and execution for you.
Prefer a fully local, account-free TongFlow? That's what self-hosting is for — see Run from source or Run with Docker, then follow Self-host setup. (The desktop app up to v0.1.13 bundled this local runtime; those installers remain on the Releases page.)
Core Concept
-
All models: AI models can be thought of as a modality transform (e.g. LLMs are text→text, image models are text→image, speech models are text→audio, and so on). TongFlow wraps each capability as a node.
-
All modalities: TongFlow supports almost every modality and file format that people actually ship over the web.
-
Low barrier, high ceiling: no complex AI parameters to learn, no manual node connecting; just three operations — add, transform, and combine — to arrange ideas freely. And by orchestrating AI models freely, you can generate unique creations and works of your own.
-
Open ecosystem: TongFlow's plugin-based design lets every platform package its own independent plugins, and we provide at least one official implementation plugin for each capability node. The core stays small, the ecosystem stays open.
What’s Defined
✅ = available out of the box with an official plugin · ⬜ = node exists in the canvas but has no official plugin yet (planned).
Add
- ✅ Text input: type text and add a text node.
- ✅ Add image: pick a local file and add an image node.
- ✅ Add photo: capture with the device camera and add an image node.
- ✅ Add sketch: draw on the canvas and add an image node.
- ✅ Add audio: pick a local audio file and add an audio node.
- ✅ Record audio: record with the mic and add an audio node.
- ✅ Add video: pick a local video file and add a video node.
- ✅ Record video: record with the camera and add a video node.
- ✅ Add document: pick a local file and add a document node.
- ✅ Add URL: fetch a page from a link and add text, image, audio, or video nodes.
- ✅ Add 3D model: choose a local model file and add a 3D model node.
Transform
Text
- ✅ Generate / rewrite: create or edit copy from a prompt.
Image
- ✅ Image generation: images from text.
- ✅ Image editing: inpaint, edit, or redraw with instructions.
- ✅ Image understanding: captions, Q&A, or descriptions from an image.
- ✅ Image upscaling: enlarge for sharper detail.
- ✅ Pose detection: 308-keypoint whole-body skeleton overlay (body, hands, face).
- ✅ Body-part segmentation: 29-class human parsing overlay.
- ✅ Surface normals: per-pixel normal map — human-centric or full scene.
- ✅ Matting: cut the human or salient foreground out as a transparent PNG.
Video
- ✅ Video generation: video from text.
- ✅ Image-to-video: animate a still into motion.
- ✅ First/last-frame video: two key images to interpolate a clip.
- ✅ Images → video: multi-image reference fusion — several reference images plus text into a new video.
- ✅ Omni-reference video: mix image, video, and audio references (plus text) into one video with native stereo audio.
- ✅ Video understanding: summaries or descriptions from video.
- ✅ Video upscaling: higher-resolution output.
- ✅ Extract first / last frame: grab a frame as an image.
- ✅ Video editing: edit a video from a text instruction.
- ✅ Subtitle removal: clean subtitles from a video.
- ✅ Watermark removal: remove watermarks from a video.
Audio
- ✅ Music generation: music from text, with optional reference-audio conditioning.
- ✅ Audio understanding: describe a clip (music, speech, or ambient sound) in text.
- ✅ Music repaint: regenerate a chosen time range of a song.
- ✅ Music cover: restyle a song via a caption and/or a reference track.
- ✅ Add track / complete arrangement: generate one new stem over a mix, or fill in missing tracks.
- ✅ Music brief: one-sentence idea → lyrics, style tags, BPM, key, and duration.
- ✅ Speech synthesis: text-to-speech — preset style, voice clone (reference audio), or instruction-driven.
- ✅ Speech recognition: transcribe speech from audio or video.
- ✅ Noise reduction: denoise audio.
- ⬜ Speaker diarization: separate audio by speaker.
- ⬜ Voice / timbre replacement: replace or clone a voice with a reference sample.
- ✅ Multi-track / vocal-accompaniment separation: isolate vocals, drums, bass, guitar, and 8 more stems.
- ✅ Open-vocabulary sound separation: describe any sound in words ("dog barking") and split the audio into that sound and everything else.
Combine
- ✅ Image fusion: blend or edit multiple references into one image.
- ✅ Lip sync: audio + video → video (lip-sync); also audio + image → video and audio + text → video variants.
- ✅ Emotive speech: text + voice reference → speech in that voice, with emotion control.
- ✅ Character swap: video + reference (scene blend / character replacement), Animate Mix-style generation.
- ✅ Motion transfer: video + reference (motion / retarget), Animate Move-style generation.
- ✅ Combine text: merge multiple text nodes into one.
Other
- ✅ Image → 3D: single-view 3D model from an image.
- ✅ Video → motion capture: monocular video to skeletal animation (body + fingers + face channels, GLB).
- ✅ Document → text: extract plain text from documents.
- ✅ Link → text: turn page content into text.
Helpers
- ✅ Concatenate clips: join multiple videos end to end.
- ✅ Mux audio + video: merge into one file.
- ✅ Split by shots: cut a long video into segments by scene.
- ✅ Split video & audio: demux a video into separate video and audio tracks.
- ✅ Extract audio track: pull audio into its own asset.
- ✅ Split long text: break a long passage into chunks.
- ✅ Merge / tidy text blocks: combine segments (use the auto-merge option).
- ✅ Filter or drop clips: drop unwanted clips by rule or selection.
- ✅ Arrange & batch groups: group and arrange text/clip batches for downstream processing.
Official plugins
The official GPU/CPU plugins currently run on Modal — up to $30/month of free GPU compute (H100/A100, etc.). See Self-host setup for the
MODAL_TOKEN_*setup. Any other platform can publish its own plugins the same way.
API plugins
First-party providers (a lab's own models):
- tongflow-api-gemini — Google Gemini with a per-node model picker: text, vision, image (Nano Banana / Imagen 4), Veo video, TTS and transcription
- tongflow-api-openai — OpenAI with a per-node model picker:
gen_text, image gen/edit/fusion (gpt-image-2), vision, document OCR, Whisper transcription and TTS - tongflow-api-deepseek — DeepSeek V4 (
flash/pro, with a streaming thinking bubble) forgen_text/ text tools - tongflow-api-bytedance — ByteDance Volcengine Ark with a per-node model picker: Doubao text & vision, Seedream image gen/edit/fusion, Seedance text/image/audio → video
- tongflow-api-xai — xAI Grok with a per-node model picker:
gen_text(Grok 4.x), image understanding, and Grok Imagine text-to-image - tongflow-api-runway — Runway Dev unified API with a per-node model picker: video (Gen-4.5, Gen-4 Turbo, Aleph edit, Act-Two, Seedance, Veo), image (GPT Image 2, Seedream 5, Gemini image 3) and ElevenLabs TTS
Router plugins
Aggregators — one key, many third-party models across labs:
- tongflow-router-openrouter — OpenRouter with a per-node model picker:
gen_text(free by default, plus GPT-5.5 / Claude / Gemini / Grok / DeepSeek), vision / audio understanding, image gen/edit and transcription - tongflow-router-cometapi — CometAPI gateway with a per-node model picker that also lists CometAPI's live catalog:
gen_text/ text tools (GPT-5.5, Claude, Gemini, DeepSeek, Grok, Qwen, Kimi), image / video / audio understanding, image gen/edit/fusion (GPT Image 2, Seedream), text / image(s) → video (Sora 2, Veo 3.1, Seedance, Wan, MiniMax, HappyHorse, Vidu), video edit (Omni), TTS and Whisper transcription - tongflow-router-toapis — ToAPIs gateway with a per-node model picker:
gen_text/ text tools (GPT-5.6, Claude, Gemini, DeepSeek, Qwen, GLM, Kimi, MiniMax), image understanding, image gen/edit/fusion (GPT Image 2, Seedream 5, Gemini Image, Flux 2, Grok), text / image(s) / first-last-frame / multimodal refs → video (Sora 2, Veo 3.1, Seedance 2, Kling, MiniMax H3, Wan, HappyHorse, Vidu), video edit (HappyHorse); the picker also lists the live per-key model list - tongflow-router-apimart — APIMart gateway with a per-node model picker: image gen/edit (Z-Image, Seedream, Nano Banana, GPT-Image), text/image → video (Kling, VEO3, Sora2, Seedance),
gen_text(GPT-5, Claude, Gemini), Whisper transcription and TTS - tongflow-router-replicate — Replicate with a per-node model picker across the catalog: text, vision, image gen/edit/fusion/upscale/matting, text/image → video, transcription, TTS / voice clone, music, and image → 3D (FLUX, Seedream, Veo, Kling, Whisper, Hunyuan3D…)
- tongflow-router-fal — fal.ai with a per-node model picker: image (gen/edit/fusion/upscale/matting/pose/normal/seg), video (text/image → video, first-last frame, talking-head, lip-sync, upscale), audio (transcription, TTS, voice clone, music, source separation) and image → 3D
GPU/CPU plugins
- tongflow-modal-ffmpeg — transcoding, muxing, media pipelines
- tongflow-modal-pyscenedetect — shot-boundary detection for splitting clips
- tongflow-modal-z-image — Z-Image text-to-image
- tongflow-modal-ernie-image — ERNIE Image text-to-image (alternative)
- tongflow-modal-krea2 — Krea 2 Turbo text-to-image (open-weights 12B, 8-step, up to 2K)
- tongflow-modal-flux2-klein9b — FLUX.2 Klein 9B multi-reference fusion / image editing
- tongflow-modal-boogu — Boogu-Image-0.1 (fp8) text-to-image (dense bilingual text) & single-reference image editing
- tongflow-modal-infinitetalk — InfiniteTalk audio-driven lip-sync (audio + image / video → talking-head video)
- tongflow-modal-wan-animate — Wan-Animate character swap & motion transfer (video + reference)
- tongflow-modal-scail2 — SCAIL-2 controlled character animation (image + driving video; same two slots as wan-animate)
- tongflow-modal-minimax-h3 — MiniMax-H3 33B video generation with native stereo audio (text / first- & last-frame / multi-image / omni-reference)
- tongflow-modal-bernini — Bernini-R 1.3B unified video renderer (text/image → image/video, video editing, subtitle / watermark removal)
- tongflow-modal-sam3 — SAM 3 / SAM 3.1 text-guided matting: cut every instance of a described concept out of an image (transparent PNG) or track it through a video (green-screen matte)
- tongflow-modal-triposplat — TripoSplat single image → 3D Gaussian splat
- tongflow-modal-sam-3d-objects — SAM 3D Objects single image → 3D Gaussian splat of the foreground object (auto mask, robust to occlusion/clutter; alternative)
- tongflow-modal-sam-3d-body — SAM 3D Body single image → full-body 3D human mesh GLB (multi-person, MHR rig; alternative), and video motion capture (per-frame MHR regression → animated character GLB; alternative)
- tongflow-modal-sapiens2 — Sapiens2 (Meta) human suite: pose detection, body-part segmentation, surface normals, human matting, image → 3D point cloud, and video motion capture (geometric engine: keypoints + pointmap → animated MHR character GLB)
- tongflow-modal-sensenova-vision — SenseNova-Vision (SenseTime) unified vision model: image understanding / visual QA, detection & OCR structured text, full-scene surface normals, salient-object matting, and human pose overlay (alternative)
- tongflow-modal-seedvr2 — SeedVR2 image / video super-resolution
- tongflow-modal-gemma4 — Gemma-4 multimodal text (image / video understanding)
- tongflow-modal-qwen38 — Qwen3.8-27B multimodal text (text generation, image / video understanding; alternative)
- tongflow-modal-qwen3asr — Qwen3 speech recognition
- tongflow-modal-qwen3tts — Qwen3 text-to-speech
- tongflow-modal-indextts2 — IndexTTS-2.5 emotive text-to-speech: zero-shot voice cloning (alternative) and emotion-controlled speech from a voice reference
- tongflow-modal-whisper — Whisper speech recognition with timestamps (alternative)
- tongflow-modal-ace-step — ACE-Step 1.5 music suite: text-to-music (sft / base / turbo selectable), repaint, cover, stem extraction, add-track, arrangement completion, music brief, and music understanding
- tongflow-modal-levo — LeVo 2 / SongGeneration text-to-music (multilingual, commercial-grade)
- tongflow-modal-minimax-music3 — MiniMax-Music3 11B song generation: lyrics + description → complete song with vocals (up to ~5 min, 32 kHz stereo)
- tongflow-modal-sam-audio — SAM-Audio text-prompted sound separation: noise reduction, vocal isolation, and free-text stem extraction ("the piano in the background")
- tongflow-modal-docling — Docling document → text
- tongflow-modal-paddle — PaddleOCR document → text
- tongflow-modal-unlimited-ocr — Unlimited-OCR long-horizon document / PDF → text
- tongflow-modal-crawl4ai — Crawl4AI URL / link → text
- tongflow-modal-scrapling — Scrapling stealth-browser URL / link → text
Run from source
pnpm install
pnpm plugins:install   # clone official plugins into plugins/
pnpm start:prod        # builds once, then serves at http://localhost:3000
Requires Node (with pnpm) and a Python 3.10+ interpreter on your PATH (set PYTHON to point at a specific one). Plugins run as local Python processes; TongFlow provisions an isolated venv for them automatically and installs each plugin's requirements.txt on first use — no manual Python setup.
Open http://localhost:3000 and the canvas is live. Then follow Self-host setup (credentials go in the in-app Settings dialog, or a project .env).
Run with Docker
A self-host image is published to GHCR — no Node/Python/pnpm setup required:
docker run -d -p 3000:3000 \
  -v tongflow-data:/data -v tongflow-plugins:/plugins \
  ghcr.io/tong-io/tongflow:latest
Then open http://localhost:3000. Or with Compose (clones this repo's docker-compose.yml):
docker compose up -d
To build the image yourself instead of pulling: docker build -t tongflow .
Data & credentials. Everything writable lives in the /data volume (SQLite db, uploads, settings). API keys are optional — set them in the in-app Settings dialog, or pass them at launch (-e OPENROUTER_API_KEY=…); supported keys: OPENROUTER_API_KEY, GEMINI_API_KEY, OPENAI_API_KEY, MODAL_TOKEN_ID / MODAL_TOKEN_SECRET.
Plugins. The image ships no plugins — install them from the in-app plugin manager (first install needs network access to GitHub). On first run, a plugin provisions a shared Python venv under /data/.tongflow/plugin-venv (installs the SDK + the plugin's requirements.txt from PyPI), so the first run is slower and needs network. Modal-backed plugins additionally need a Modal token.
Self-host setup (plugins & credentials)
A self-hosted TongFlow ships with no plugins pre-installed, and the canvas is preloaded with an example workflow. Three steps get it running:
1 — Install plugins
Open the plugin manager (the blocks icon, top-right) and install what you need. Newly installed plugins are usable immediately, no restart.
To run the preloaded example workflow (text → image → fusion → video), install these three plugins:
- tongflow-modal-z-image — text-to-image
- tongflow-modal-flux2-klein9b — image fusion / blending
- tongflow-modal-minimax-h3 — image-to-video
These run on Modal (up to $30/month of free GPU compute). Add MODAL_TOKEN_ID / MODAL_TOKEN_SECRET in Settings; create a token at modal.com/settings/tokens. Any other platform can publish its own plugins the same way.
Browse the full catalog — the official API plugins (OpenAI / Gemini / OpenRouter) and other GPU/CPU plugins — in the plugin manager.
2 — Configure credentials
Open Settings (the gear icon, top-right) and add the environment variables your plugins need — e.g. OPENAI_API_KEY for the API plugins, or the credentials your GPU/CPU plugins require.
Plugin credentials live in Settings. TongFlow is platform-agnostic and hardcodes no provider: the Settings dialog is a generic key/value editor for environment variables passed to plugins. Each plugin's README documents the keys it needs. Values are stored locally and take effect without a restart.
3 — Run the example workflow
Run the preloaded example node by node, or switch to Execute Mode and hit the run button to run the whole thing in one click.
Custom plugins
Every runnable node is backed by a contract — the ABI (packages/tongflow/abi/tongflow.abi.json) — that defines what capabilities exist and what each one's input/output looks like, independent of who implements it. A plugin is just a small Python package that picks one or more ABI slots and supplies the how, annotated against the ABI-generated types via the tongflow Python SDK.
The full development flow — the ABI, the @node_slot decorator, the SDK, directory layout, and how to publish — lives in docs/plugins.md.
Community
Join the community on Discord or scan the WeChat group QR code below.
Business
For business inquiries, please contact [email protected].
- Open-source model owners: I can integrate your models so users can try them out smoothly.
- Enterprise: I can help you deploy on your local GPU, build custom nodes and plugins, and more.
- Platform / router: I can integrate your APIs.
- VCs: I’m interested in partnering on tongflow.com, a cloud-hosted AI studio.
Open-Source
If you like this project, a Star on GitHub helps a lot. Thank you.
License
TongFlow is dual-licensed:
- AGPL-3.0 — free for individuals, research, open-source projects, and anyone willing to comply with the AGPL (including its Section 13 network/source-disclosure obligation).
- Commercial License — for organizations that want to use TongFlow in closed-source or SaaS products without AGPL's source-disclosure obligation, or that need warranties and platform support. Contact [email protected].
This covers the entire repository, including the sdk/ directory (the tongflow
PyPI package). Contributions are covered by our CLA.
Read the usage guide →
Install steps, key points, FAQ and compatibility for this plugin — auto-derived from indexed fields.
Listing badge

[](https://deepseek-plugin.org/plugins/tong-io/tongflow/packages/dsh-tongflow)Paste this markdown into your GitHub README to link back to this listing. The badge only states the listing — not a security endorsement.